The models are measurable. Why aren’t we?
AI companies measure their models constantly: benchmarks, latency, accuracy, cost. But when a person sits down to use one, nothing measures how well that person is working with it.
That’s the half we care about, and it’s why we started Worsley.
We couldn’t see our own habits.
Most of us spend hours a week prompting AI. A conversation can take two prompts or twenty: you change direction, add context, fix a misunderstanding, attach a file, switch models, start over.
When it ends, all of that becomes a chat history nobody rereads. You can see the answer you got. You can’t see whether you got there well, or whether you make the same mistakes every week.

So we built an instrument panel.
Worsley runs alongside the AI tools you already use and records each conversation, so you can look at it afterwards. It doesn’t judge whether ChatGPT gave a good answer. It looks at how you prompted.
One session on its own doesn’t tell you much. Over a few weeks patterns show up, and a pattern is something you can actually work on.
ROIP
We needed a name for what we were measuring, so we called it Return on Iterative Prompting.
It scores the whole conversation rather than a single prompt, because almost nobody gets a good result from one “perfect” prompt. It grades each turn on whether the prompt gave the AI what that turn needed, judged against seven criteria:
- Direction
- What the task is and what it's for: the request, the goal, and what a vague word like “better” means.
- Context
- The facts about your situation the model can't know: the material, the audience, what you've tried.
- Format
- The shape of the answer: its structure, the parts it must have, and its length.
- Constraints
- What's off-limits and the bounds: what must not change, budgets, deadlines, rules to follow.
- Examples
- A sample of what good looks like: a past email, a slide, an input with its output.
- Evaluation
- How to tell the answer worked: the test it should pass, what would make it ready.
- Task Decomposition
- Splitting work too big for one prompt into steps, one at a time.
Why Worsley?
Worsley is named after Frank Worsley, captain of Endurance and navigator of the James Caird during Shackleton’s Imperial Trans-Antarctic Expedition.
His navigation helped guide the crew across the Southern Ocean under extraordinarily difficult conditions.
He is widely regarded as one of the greatest navigators of all time.
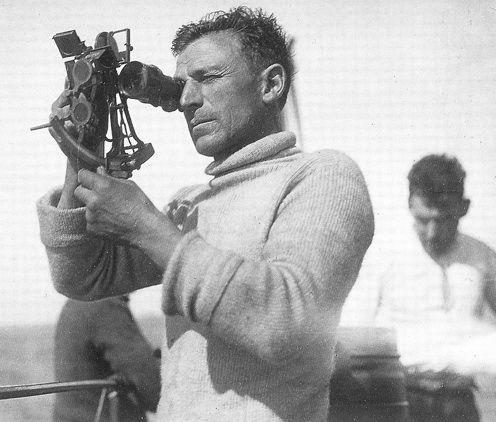
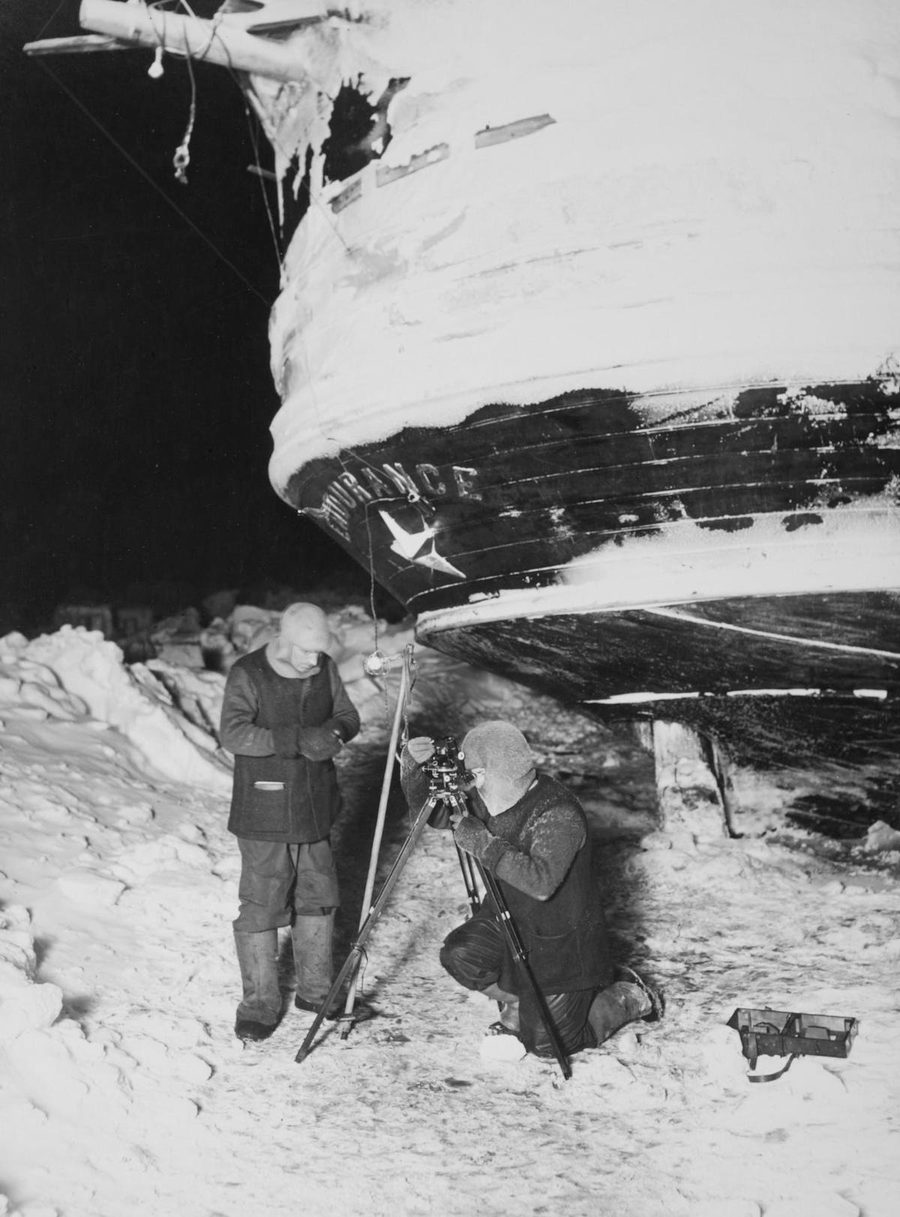
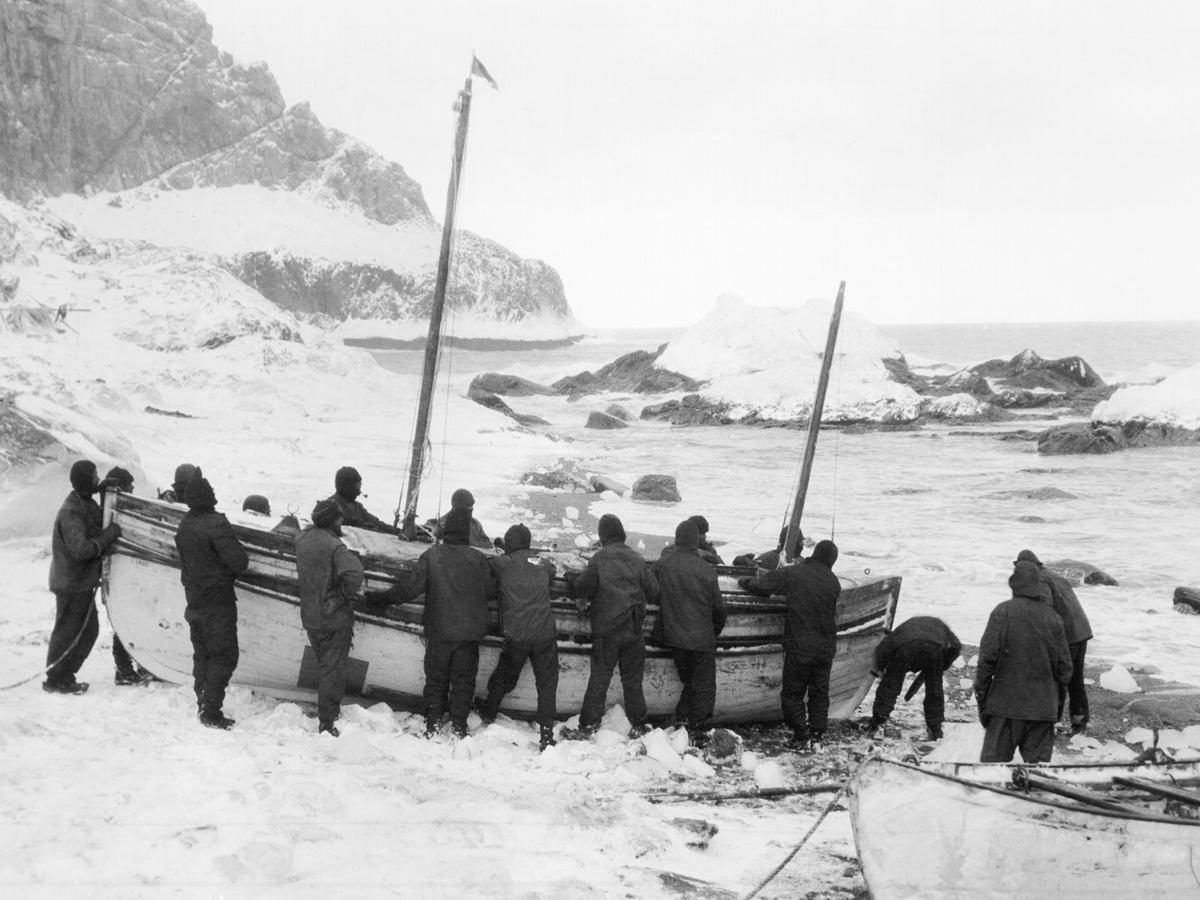
The tools have changed. The principle hasn’t. Better navigation leads to better outcomes.
What you get with Worsley
Worsley is a browser extension, a terminal connection and a dashboard. The extension captures your conversations in the AI tools you already use in the browser, and the terminal connection captures the AI sessions you run in your terminal. The dashboard scores each one with ROIP and walks you through it turn by turn: what moved it forward, where it drifted, and what to try next time.
Over a few weeks you see your patterns: where your time goes, which models you lean on, and which habits raise your score. For teams, the same view shows what the team does well and what to coach next.